 Tutorials
Intermediate
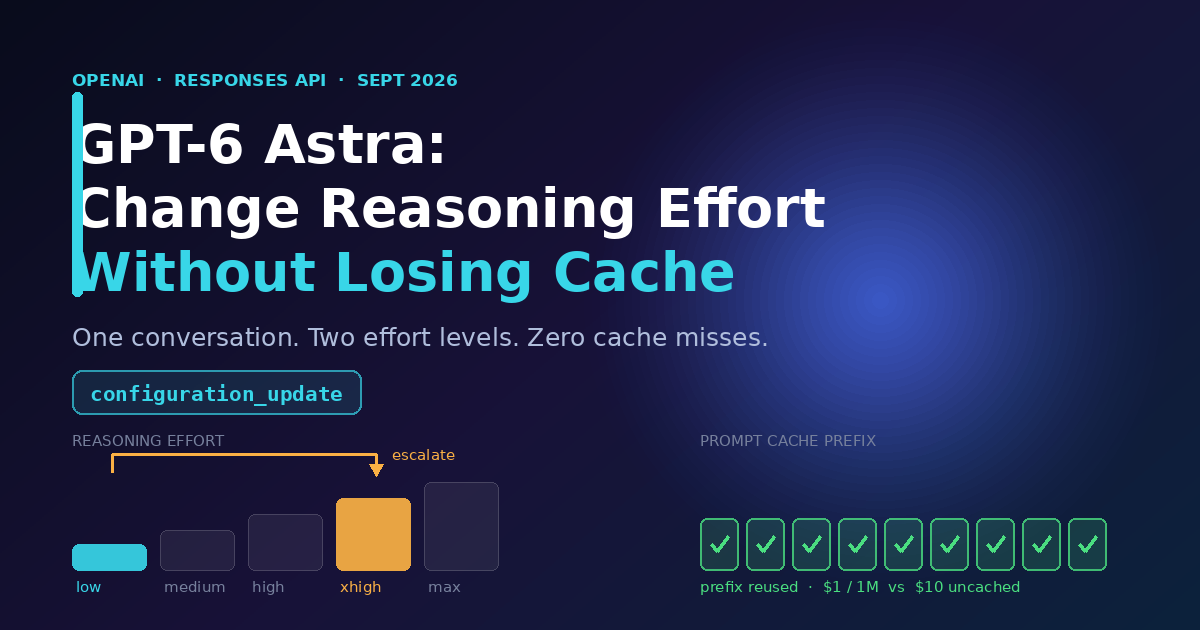
GPT-6 Astra: Change Reasoning Effort Without Losing Cache
Use configuration_update to raise or lower Astra's reasoning effort mid-chat and keep cache hits.
11 min read·Kodetra Technologies
4d agoHow-to content for builders, indie hackers, and AI engineers. Less theory, more shipped code.
Tutorials Use configuration_update to raise or lower Astra's reasoning effort mid-chat and keep cache hits.
 Tutorials
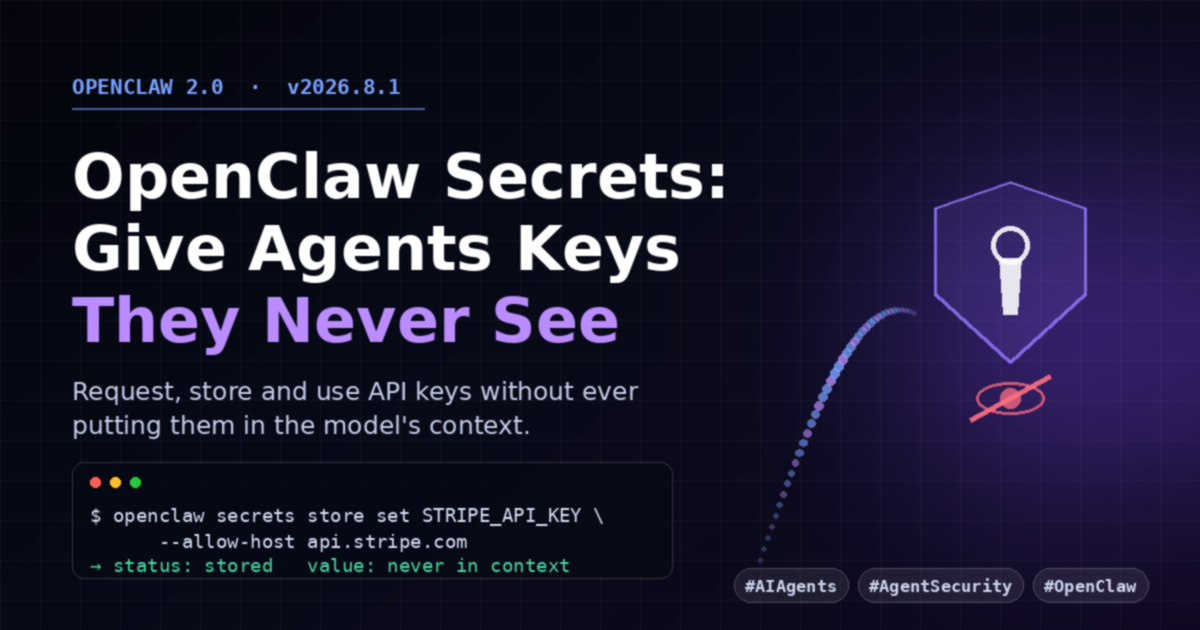
Use OpenClaw 2.0's secrets tool and egress proxy so agents use API keys without ever reading them.
 Tutorials
Keep long-running Grok 4.6 agents cheap: cache keys, token budgets, and the 200K cliff.
 Tutorials
Build a Python gate that scans MCP tool descriptions for hidden injections and pins them by hash.
 Tutorials
Wire Anthropic's /security-review and GitHub Action to catch SQLi, XSS and RCE before merge.
 Tutorials
Structure prompts so DeepSeek's disk cache hits, and pay ~50x less on repeated input tokens.
 Tutorials
Add or drop Claude Opus 5 tools between turns without invalidating your prompt cache.
 Tutorials
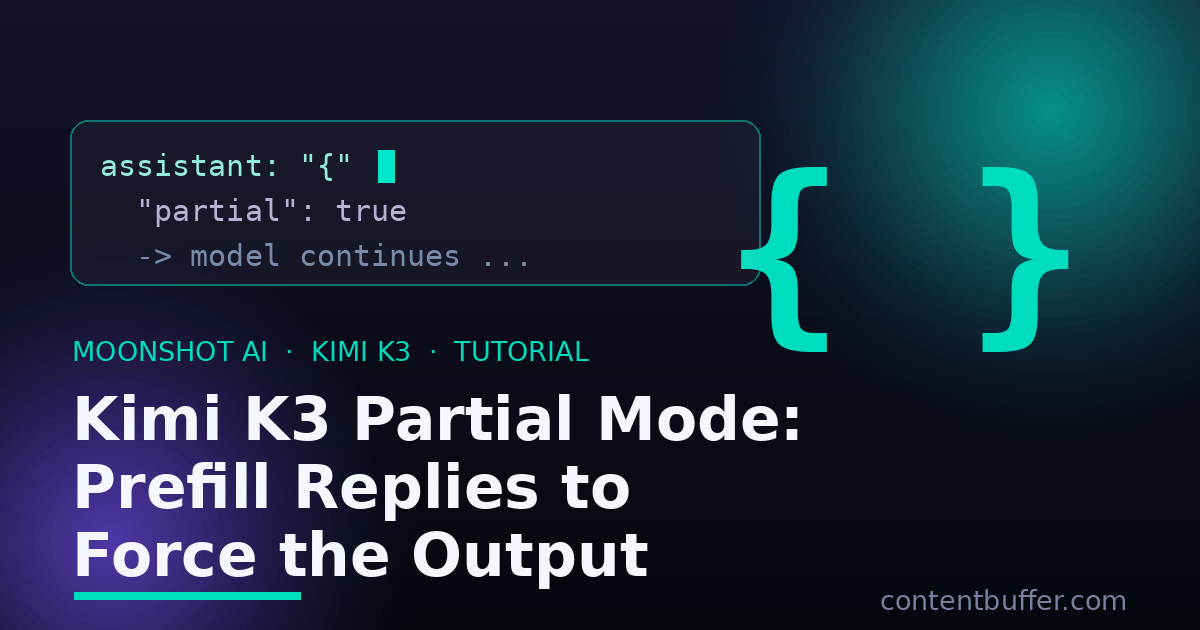
Prefill Kimi K3's assistant turn to lock output shape, force clean JSON, and steer tone.
 Tutorials
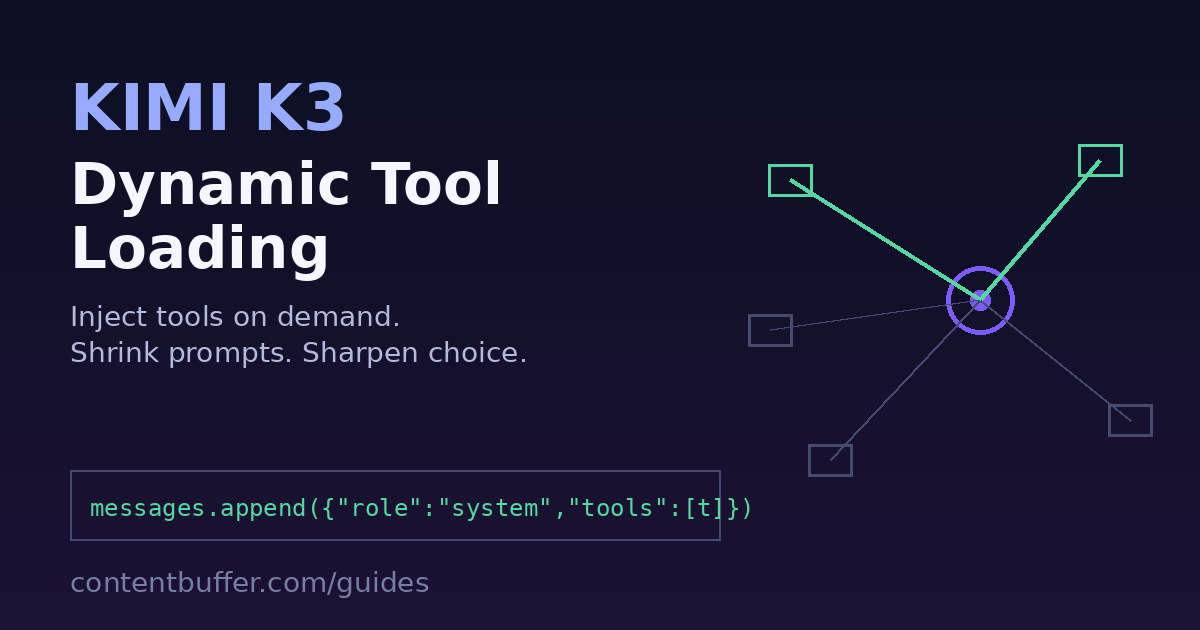
Load tools just-in-time in Kimi K3's agent loop to shrink prompts and sharpen tool choice.
 Tutorials
Point the OpenAI SDK at Moonshot's 2.8T K3, load a whole repo, and cut cost with caching.
 Tutorials
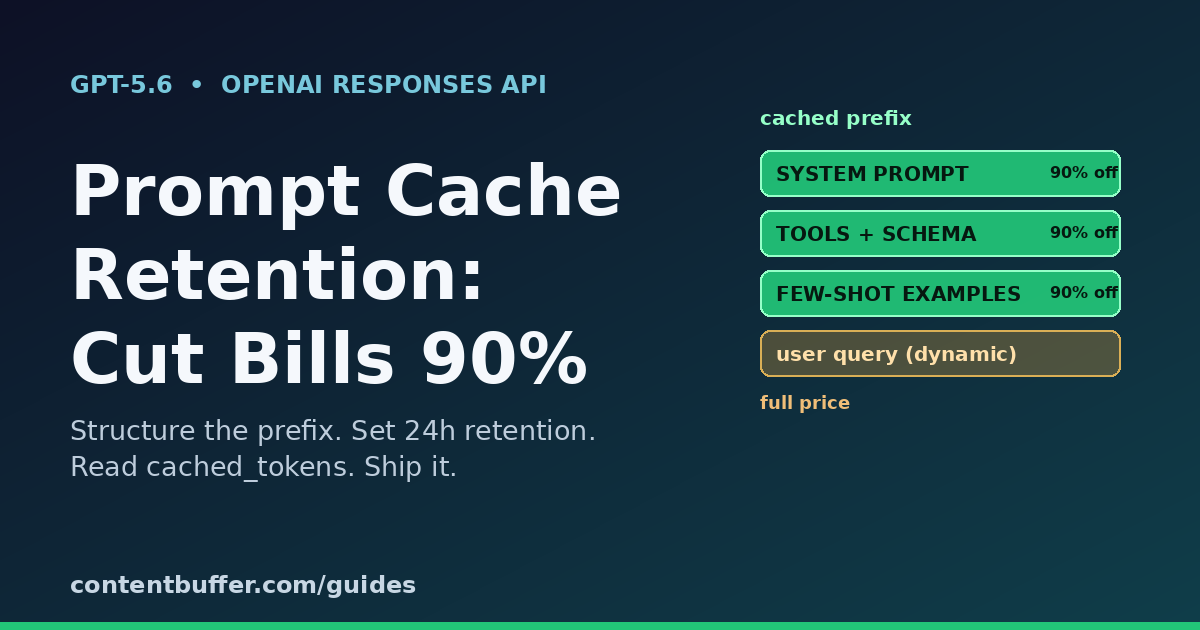
Structure prompts, set prompt_cache_retention, and read cached_tokens to slash GPT-5.6 input costs.
 Tutorials
Build an agentic Grok 4.5 tool loop in Python: route reasoning_effort and cache to slash cost.