🤖Gemma Transcribe Turns Embedding Model Into Speech-to-Text
Speech-to-text gets a new, faster player
TL;DR
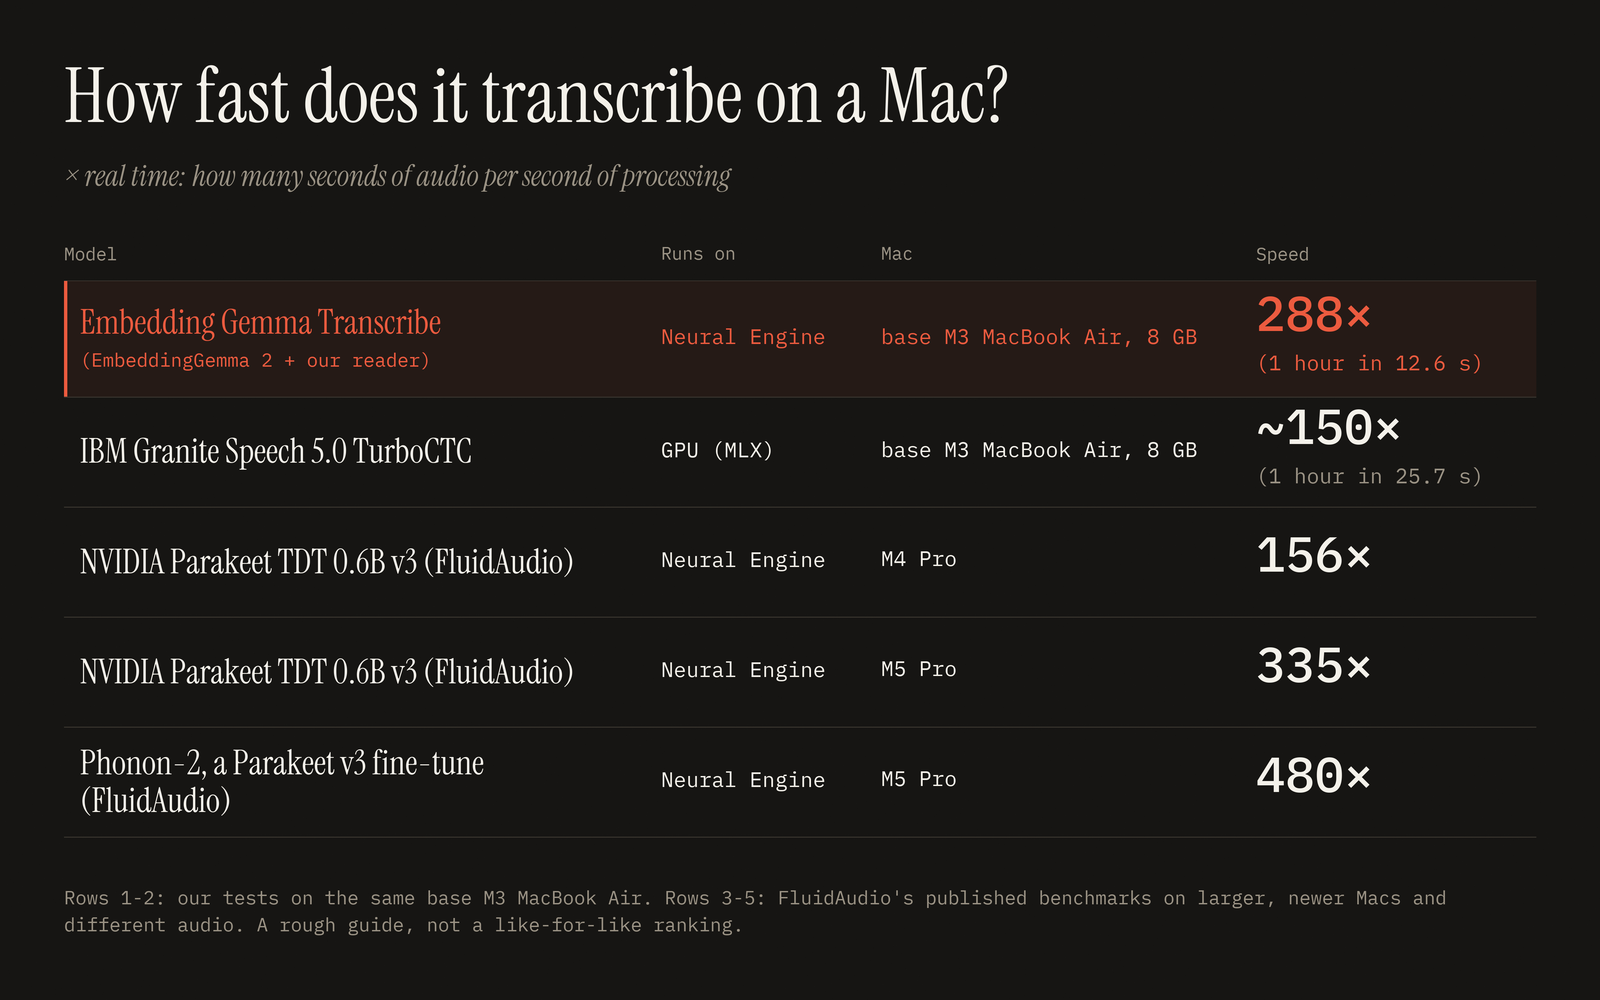
Gemma Transcribe turns an embedding model into speech-to-text, transcribing audio in 13 seconds on a MacBook Air. It's 156-480 times faster than leading models but has a 5% word error rate compared to 2-3%. Next up: better training for the reader model.
Gemma Transcribe, an embedding model, has been repurposed into a speech-to-text system. It transcribes audio in about 13 seconds on a base MacBook Air, making it 156-480 times faster than leading models like IBM Granite Speech and NVIDIA Parakeet. However, with a word error rate of 5%, it's still behind the leading models at 2-3%. The next iteration will focus on improving the reader model to close this gap. Developers using speech-to-text for real-time applications should pay attention to this new, fast player in the field.
Key Points
Gemma Transcribe transcribes speech in 13 seconds on a base MacBook Air.
Word error rate is currently around 5%, compared to 2-3% for leading models.
Next iteration focuses on improving the reader model, potentially closing the gap.
Performance is 156-480 times faster than IBM Granite Speech 5.0 Turbo CTC GPU.
Model processes audio in real-time, with seconds of audio per second of processing.
Why It Matters
If you're working with real-time speech-to-text applications, Gemma Transcribe offers a significant speed boost. However, with a 5% word error rate, it's best for non-critical applications. The model's performance is comparable to other speech-to-text models, but the faster processing time could make it a game changer for developers looking to speed up their workflows.
Comments
Be the first to comment
Enjoyed this article?
Get it daily. 7am. Free. Reads in 5 minutes.
Join 3,568 builders reading daily.