🔥Meta Finishes Phase One of 1-Gigawatt Prometheus AI Supercluster in Ohio
Meta's training cluster just got a lot more interesting
TL;DR
Meta has finished phase one of Prometheus, a gigawatt-scale AI supercluster in New Albany, Ohio, running NVIDIA GB200 and GB300 NVL72 racks. The full build targets roughly 1 million GPUs working in lockstep. If you train large models, the reliability numbers are the part to read.
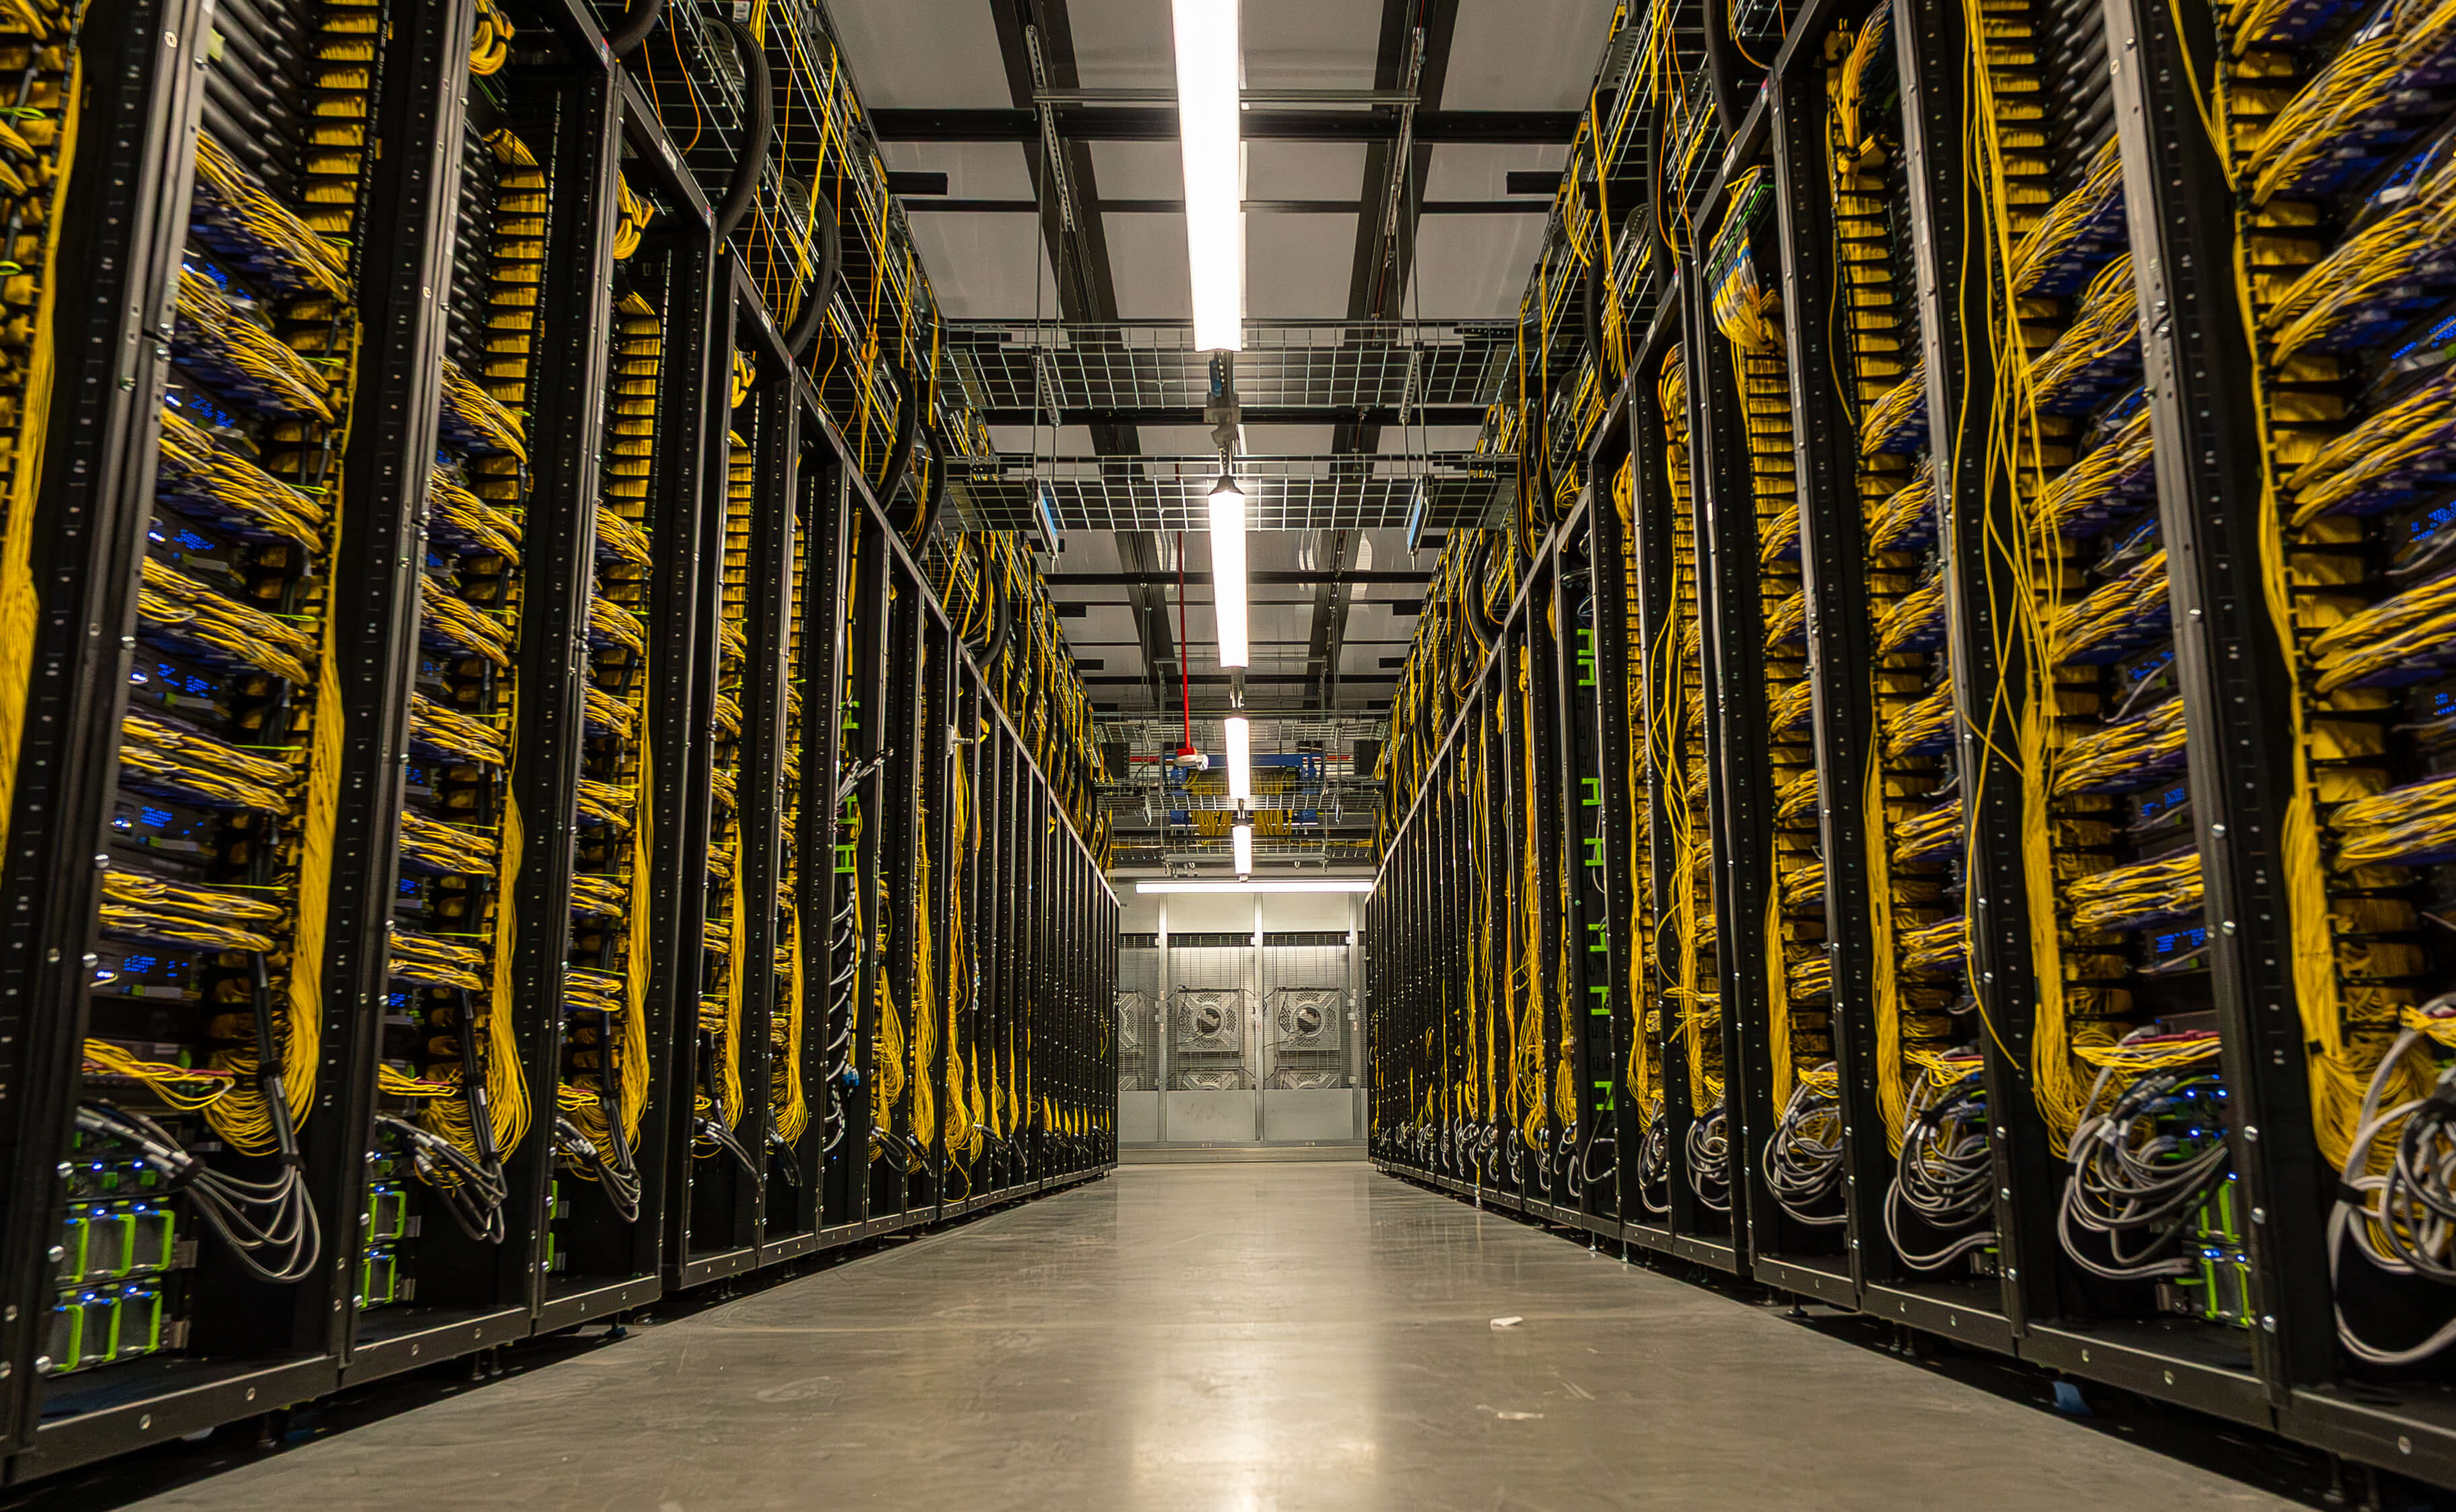
Meta just finished phase one of Prometheus, a gigawatt-scale supercluster in New Albany, Ohio. It's already running, and the target is roughly 1 million GPUs working in lockstep. Why should you care? Because the design choices are the interesting part. Meta built the network to match the hierarchy of large training jobs and to minimize exposure of any communication, so GPUs spend less time waiting. If you're planning multi-building training runs, this is a preview of how the hyperscalers are thinking about interconnect and fault tolerance. The hardware is two NVIDIA platforms now, with a third coming. Catalina uses GB200 NVL72, where the Ariel variant pairs each Blackwell GPU with a Grace CPU and 800G of I/O per GPU. Clemente moves to GB300 NVL72, lifting HBM per GPU from 192 GB to 288 GB and doubling softmax attention acceleration. Meta targets over 85% goodput for pre-training and over 90% for RL runs, with MTBI climbing from about 47K to more than 54K GPU hours after firmware fixes. Watch the goodput numbers. Those are targets, not measurements, and the full scale is still ahead.
Key Points
Phase one of Prometheus is complete at Meta's New Albany, Ohio data center, with closed-loop liquid cooling keeping the gigawatt-scale cluster running efficiently.
Keep reading — it's free
Enter your email to keep reading — plus the best of AI & tech, daily. Free, forever.
Already a member? Sign in
Comments
Be the first to comment