🤖Transformer Architecture Powers AI Models Like GPT-2
The backbone of modern AI is about to get even more powerful
TL;DR
The Transformer architecture, introduced in 2017, powers today's AI models like GPT-2. It uses self-attention to capture context, making it versatile across domains. GPT-2's small model, with 124M parameters, sets the standard.
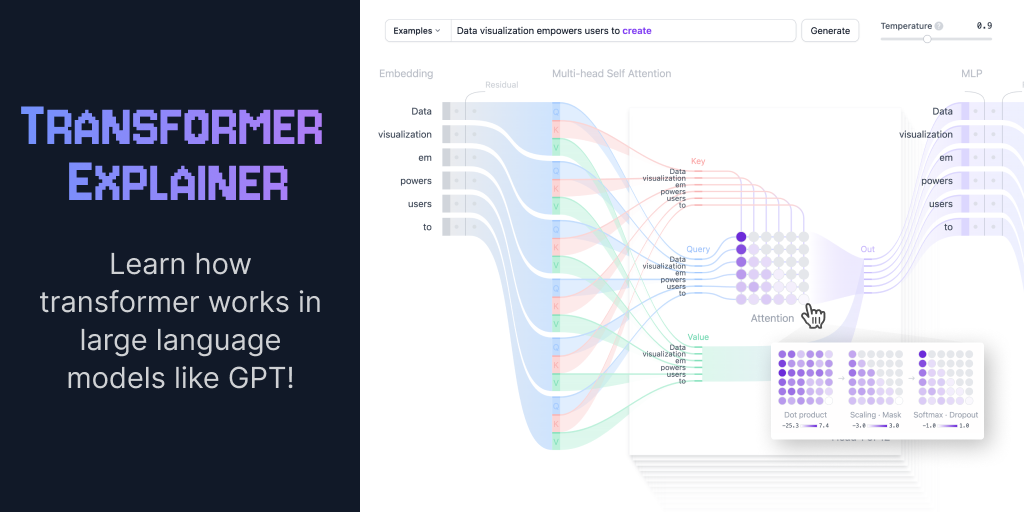
The Transformer architecture, introduced in 2017, has become the backbone of modern AI, powering models like GPT-2. This architecture uses self-attention to capture context, making it versatile for tasks like text generation, image recognition, and more. The GPT-2 small model, with 124 million parameters, consists of 12 Transformer blocks and 12 attention heads. This architecture is crucial for developers working with AI, as it enables more efficient and context-aware models. If you're building AI applications, understanding the Transformer's self-attention mechanism is key to leveraging its power.
Key Points
Transformer architecture introduced in 2017, powering AI models like GPT-2.
GPT-2 small model has 124 million parameters, 12 Transformer blocks, 12 attention heads.
Self-attention mechanism captures context, enabling efficient and context-aware models.
GPT-2 small model represents each token as a 768-dimensional vector.
Transformer architecture is crucial for developers working with AI applications.
Why It Matters
If you're building AI applications, understanding the Transformer's self-attention mechanism is key to leveraging its power. The GPT-2 small model, with 124 million parameters, sets the standard for efficiency and context-awareness. Developers working with text generation, image recognition, and other tasks should familiarize themselves with this architecture.
Comments
Be the first to comment
Enjoyed this article?
Get it daily. 7am. Free. Reads in 5 minutes.
Join 3,484 builders reading daily.