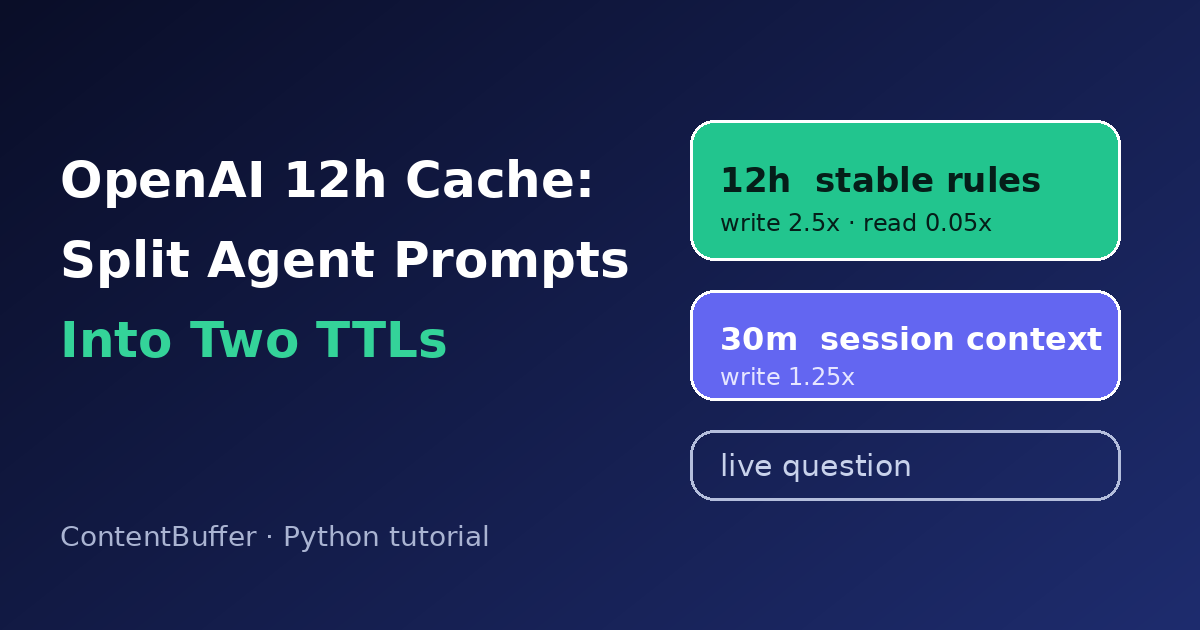
OpenAI 12h Cache: Split Agent Prompts Into Two TTLs
Summary
Use OpenAI's new 12-hour prompt cache for stable context, 30 minutes for the rest.
On October 20, OpenAI added a second lifetime for the prompt cache in the Responses API: 12 hours, next to the default 30 minutes. The changelog entry is short, but the pricing change behind it matters more than the headline. A 12-hour write costs 2.5x the normal input price, and a read costs a tenth of it (a twentieth on GPT-6.1 Sol and Terra). Whether that is a bargain depends entirely on how your agent's traffic is shaped.
This week the cache is also what people are arguing about after the news that OpenAI and Anthropic cut prices by up to 80% in a few months. Cheaper tokens help, but an agent that re-sends a 40K-token rulebook every run is still paying full freight for text that never changes. Here you will build a request that gives slow-changing context a 12-hour breakpoint and fast-changing context a 30-minute one, then log real usage and prove the savings with a cost model you can run offline.
Keep reading — it's free
Enter your email to keep reading — plus the best of AI & tech, daily. Free, forever.
Already a member? Sign in
Comments
Be the first to comment