 Machine Learning
Intermediate
Inkling 2 Small: Tune Reasoning Effort, Pay Less Per Answer
Sweep Inkling 2 Small's effort dial through Tinker's OpenAI endpoint, then route by cost.
10 min read·Kodetra Technologies
TodayHow-to content for builders, indie hackers, and AI engineers. Less theory, more shipped code.
Machine Learning Sweep Inkling 2 Small's effort dial through Tinker's OpenAI endpoint, then route by cost.
 Tutorials
Read invoice images with gpt-6.1-terra, sweep reasoning effort, escalate only when math fails.
 Tutorials
Measure what DeepSeek V4.1-Flash-1017 really costs per solved task at each reasoning effort.
 Tutorials
Build an effort-routing tool-loop client for Beam's OpenAI-compatible API and size the self-host bill.
 Tutorials
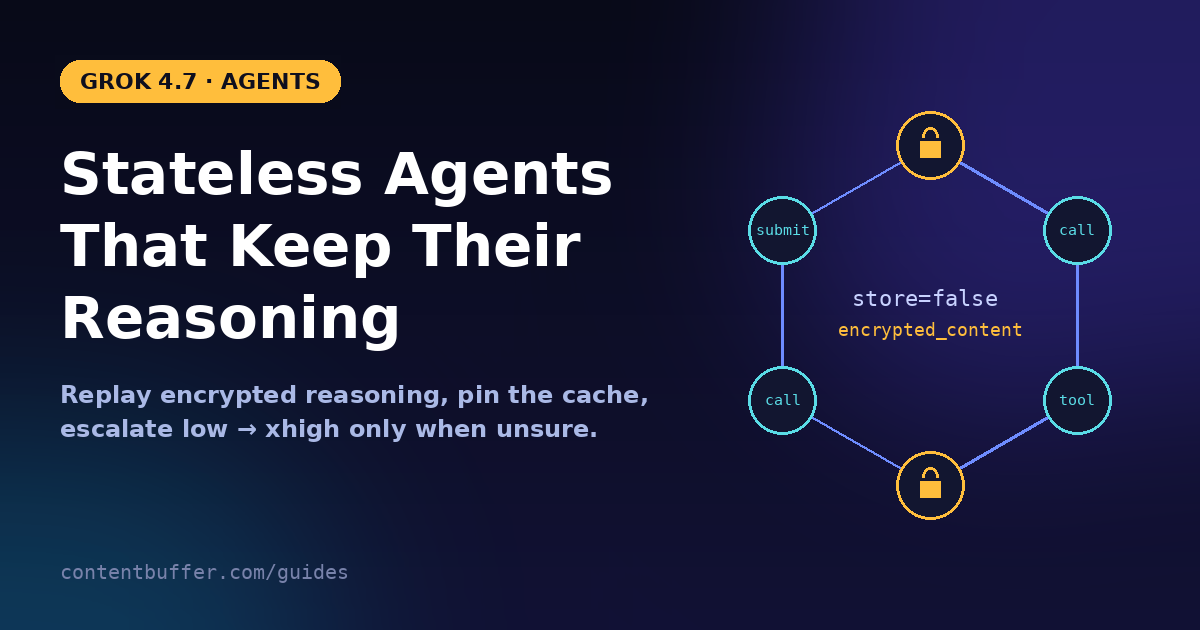
Build a store=false Grok 4.7 tool agent that keeps its reasoning, hits cache, and escalates effort.
 Tutorials
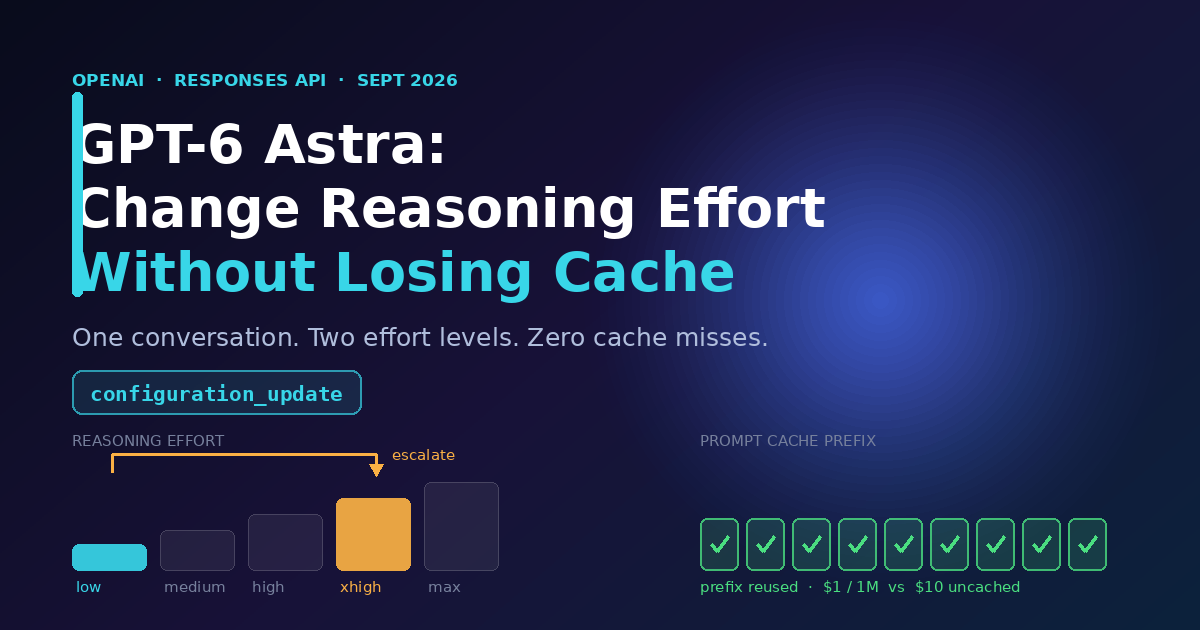
Use configuration_update to raise or lower Astra's reasoning effort mid-chat and keep cache hits.
 Tutorials
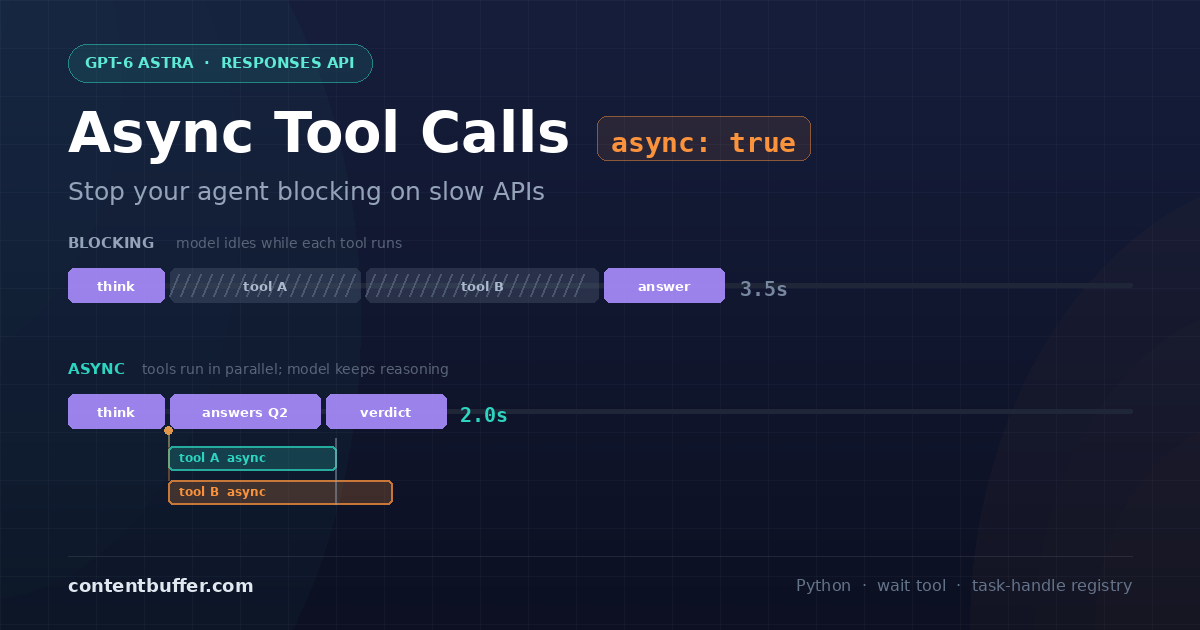
Use async tool calls and a wait tool to keep your agent reasoning while tools run.
 Tutorials
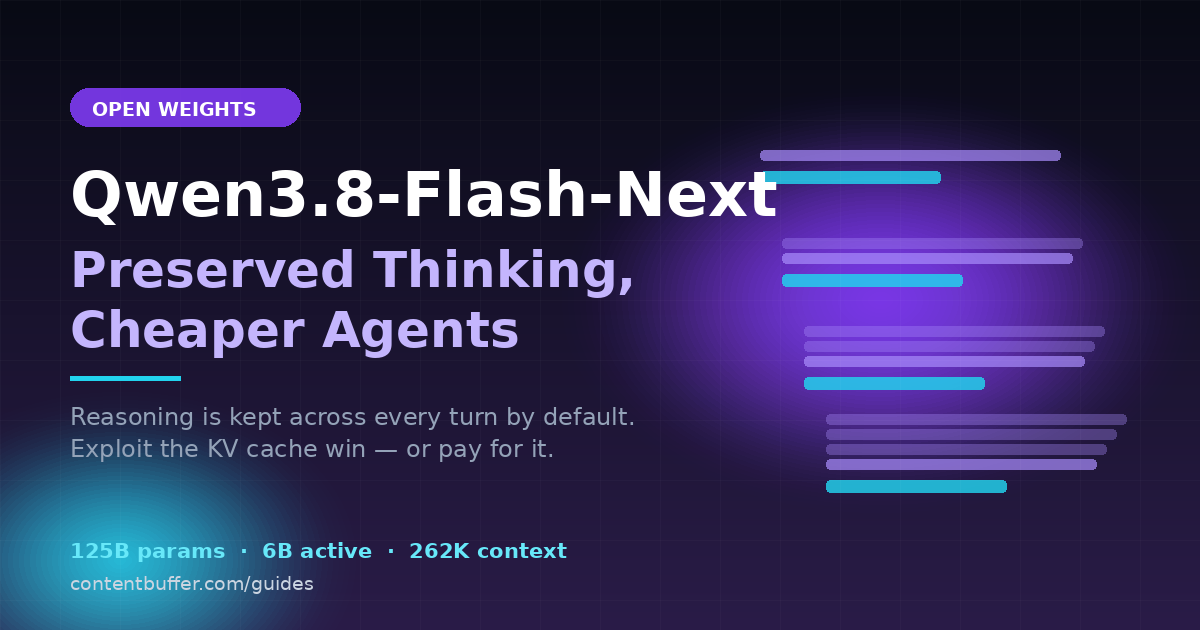
Qwen keeps reasoning across every turn by default. Exploit it, or pay for it.
 Tutorials
Tune Kimi K3's low/high/max reasoning effort and stream reasoning_content to control token cost.
 Tutorials
kimi-k3 is not a drop-in swap. Map the params right and dodge the trap that breaks tool loops.
 Tutorials
Use reasoning.context to reuse GPT-5.6's chain of thought across turns and cut redundant tokens.
 Tutorials
Build an agentic Grok 4.5 tool loop in Python: route reasoning_effort and cache to slash cost.