 Tutorials
Intermediate
OpenAI Ultrafast: Pay 6x Only When Latency Matters
A Python router that buys Ultrafast speed only where users wait, with fallback and cost tracking.
9 min read·Kodetra Technologies
5d agoHow-to content for builders, indie hackers, and AI engineers. Less theory, more shipped code.
Tutorials A Python router that buys Ultrafast speed only where users wait, with fallback and cost tracking.
 Tutorials
Fireworks' Ember-1 claims 40% fewer tokens than Kimi K3. Build a harness to verify it.
 Machine Learning
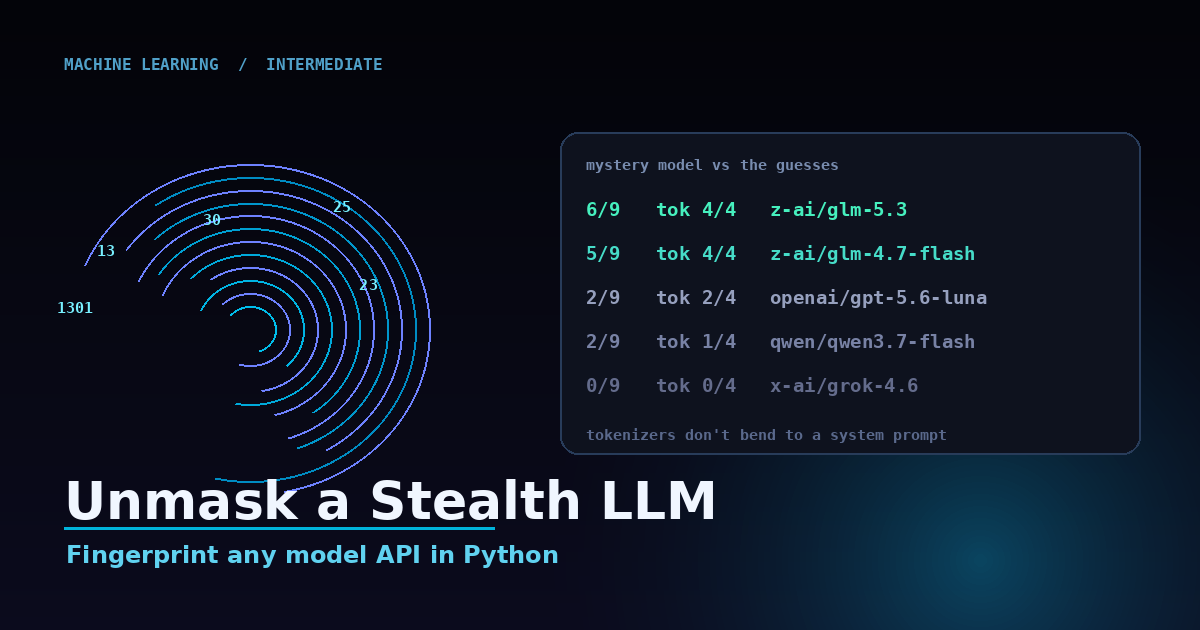
Port the Ox Alpha probe kit to Python: normalized token counts, error DNA, ranked verdict.
 Tutorials
Keep long-running Grok 4.6 agents cheap: cache keys, token budgets, and the 200K cliff.
 Tutorials
Structure prompts so DeepSeek's disk cache hits, and pay ~50x less on repeated input tokens.
 Tutorials
Route each task to the right Claude Opus 5 effort level and cut your token bill.
 Tutorials
Build a token-thrifty tool-calling agent on Gemini 3.6 Flash using the new thinking_level control.
 Tutorials
Tune Kimi K3's low/high/max reasoning effort and stream reasoning_content to control token cost.
 Tutorials
Point the OpenAI SDK at Moonshot's 2.8T K3, load a whole repo, and cut cost with caching.
 Tutorials
Point the OpenAI SDK at Meta's agent model, add tools, let it self-manage a 1M-token context.
 Tutorials
Use reasoning.context to reuse GPT-5.6's chain of thought across turns and cut redundant tokens.
 Tutorials
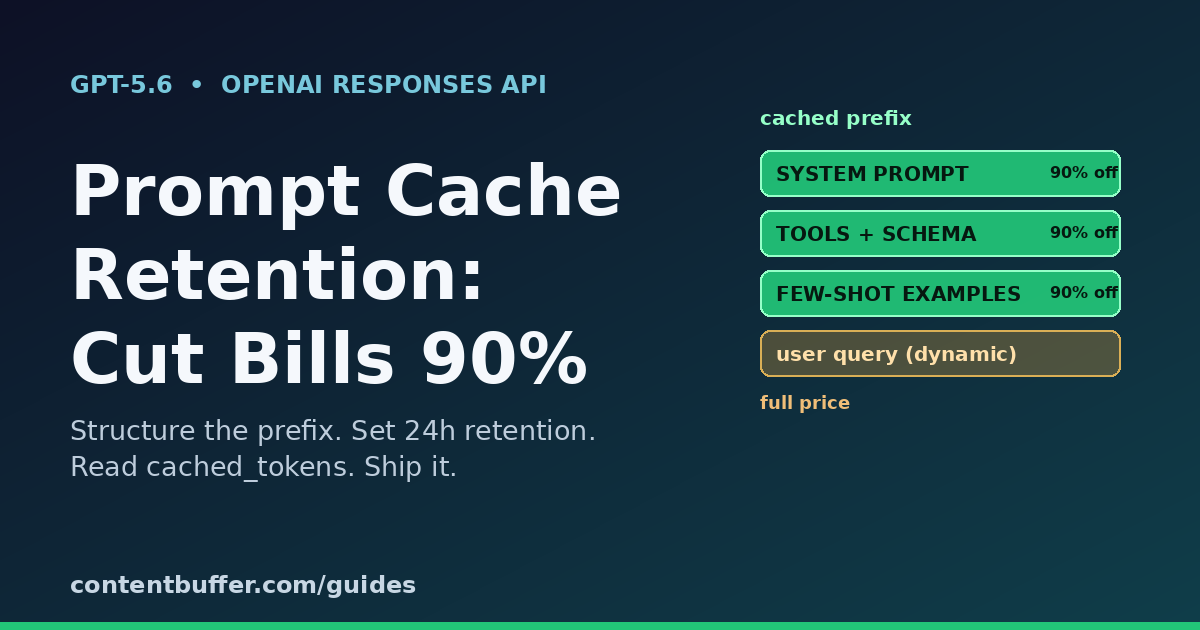
Structure prompts, set prompt_cache_retention, and read cached_tokens to slash GPT-5.6 input costs.